EIC AI Background
Moved
This site moved to https://sroai.github.io/ai-epic-background/. This copy is archived and no longer updated.
Full-simulation pipelines and CSV-based machine-learning datasets for the ePIC detector at the Electron-Ion Collider.
What is this project?
This site documents the EIC AI Background project — a set of tools for producing and consuming background-rich datasets from full ePIC detector simulations, with a focus on use cases for AI / ML training and physics studies of detector occupancy.
The work has three pillars:
simulation-pipeline/— a shared submodule of orchestration scripts that drive the ePIC simulation chain (afterburner→npsim→EICrecon) on the JLab farm and produce reconstructededm4eicROOT files for one or more beam-energy campaigns.simulation-pipeline/csv_convert/— a set of C++/ROOT converter macros (edm4eic_*/edm4hep_*), driven by40_csv_convert.py, that flatten those ROOT files into CSV: one macro per role (tracker hits, reco particles, DIS kinematics, …), each row carrying the linkedMCParticletruth.analyses/— standalone Python analyses on the produced CSVs. Each analysis lives in its own subfolder with its scripts and a short README.
The CSV output is deliberately simple so it can be consumed by Python, by LLM-generated plotting scripts, or fed directly into a torch.utils.data.Dataset for ML training.
Quick links
- Full-Sim Pipeline overview — end-to-end ePIC simulation chain runnable on JLab SLURM with reproducible per-campaign configs.
- Backgrounds — how signal events get mixed with the official ePIC background cocktails into 2 µs timeframes, with all the flags and references.
- CSV Convert — lightweight C++/ROOT converter that turns edm4eic ROOT files into flat CSV with full hit, particle, and detector context.
- AI / ML datasets — tracker hits, MC truth, and detector tags packed into CSVs that load directly into pandas, numpy, or PyTorch dataloaders.
- Available datasets — current background-mixed datasets on Rucio.
- Data format — exact column layout produced by the converter.
Pipeline at a glance
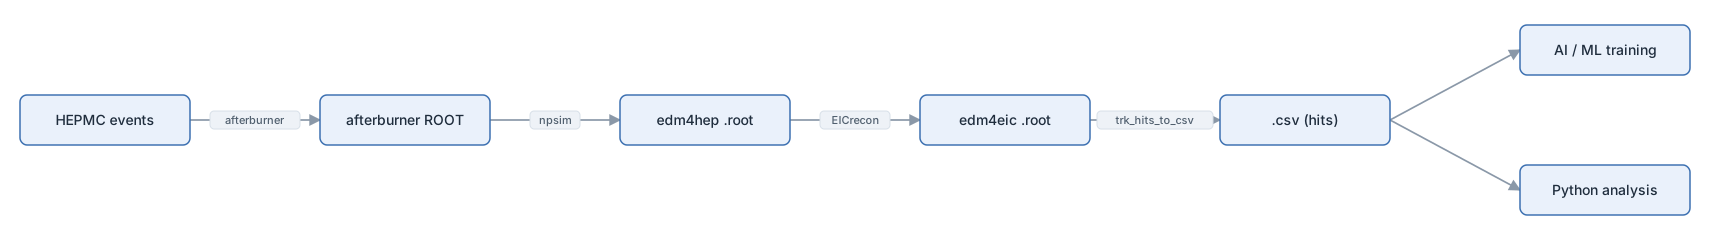
For the background-mixing step that sits between afterburner and npsim, see the Backgrounds page.
Why CSV?
Tracker-hit CSVs are dead simple to produce in C++ (no extra dependencies beyond fmt::format) and trivial to load anywhere downstream:
pandas.read_csv()for exploration and plottingnumpy.loadtxt/pyarrowfor bulk numeric work- A few lines of Python for
torch.utils.data.Dataset - LLM-generated analysis scripts, which work much more reliably on flat CSV than on EDM4EIC's PODIO graph
See the Data Format page for the exact column layout produced by the converter.
Reproducibility
The entire chain is reproducible by design:
- Pinned
eic_xlSingularity containers — every job runs in the same image. - SLURM job arrays for every stage, including CSV conversion.
- One self-contained YAML campaign config per release, checked into the repo.
So any run can be re-executed at any time, against the exact container and detector release it was originally produced with.
Project structure
ai-epic-background/
├── simulation-pipeline/          # shared submodule: ePIC simulation orchestration
│   ├── simulation_pipeline/      # stage job generators (run as scripts)
│   │   ├── 10_create_afterburner_jobs.py
│   │   ├── 11_create_background_jobs.py
│   │   ├── 20_create_npsim_jobs.py
│   │   ├── 21_create_npsim_saveall_jobs.py
│   │   ├── 22_create_npsim_background_jobs.py
│   │   ├── 30_create_eicrecon_jobs.py
│   │   ├── 40_csv_convert.py      # ONE csv script for all csv stages
│   │   ├── generate_datasets.py   # dataset-card producer
│   │   ├── datasets.py            # card schema / config loader
│   │   └── job_creator.py         # SLURM job-array engine
│   ├── csv_convert/               # ROOT → CSV converter macros
│   │   ├── edm4eic_trk_hits.cxx
│   │   ├── edm4eic_reco_particles.cxx
│   │   └── edm4hep_*.cxx / edm4eic_*.cxx
│   └── configs/                   # one self-contained YAML per campaign
├── analyses/                      # Python analyses (one subfolder each)
│   └── time-vs-z-plots/
│       └── background_analysis.py
├── docs/                          # this VitePress site
└── .github/workflows/             # GitHub Pages deployment
Where to start
- New here? Start with the Full-Sim Pipeline overview.
- Want to know how backgrounds are mixed? Go to Backgrounds.
- Looking for the data itself? See Available datasets.
- Just want flat CSV out of an existing ROOT file? Jump to CSV Convert.