Full-Sim Pipeline
The simulation-pipeline submodule orchestrates the full ePIC simulation chain end-to-end: from generator-level HEPMC files, through afterburner beam effects, through npsim (Geant4) detector simulation, through EICrecon reconstruction, and finally to CSV files for downstream analysis. It is a shared repo consumed by both ai-epic-background and meson-structure, and replaces the duplicated full-sim-pipeline/ that used to live in each project.
It is implemented as a small set of Python job-creation scripts (in the simulation_pipeline/ package) that consume a single per-campaign YAML config and emit one Singularity-wrapped script per input file plus SLURM job-array submitters. From the afterburner stage onward, stages read dataset cards (small YAML files with a files: list) rather than globbing directories themselves — the cards are produced by generate_datasets (local glob, --rucio, or explicit --files).
Pipeline stages
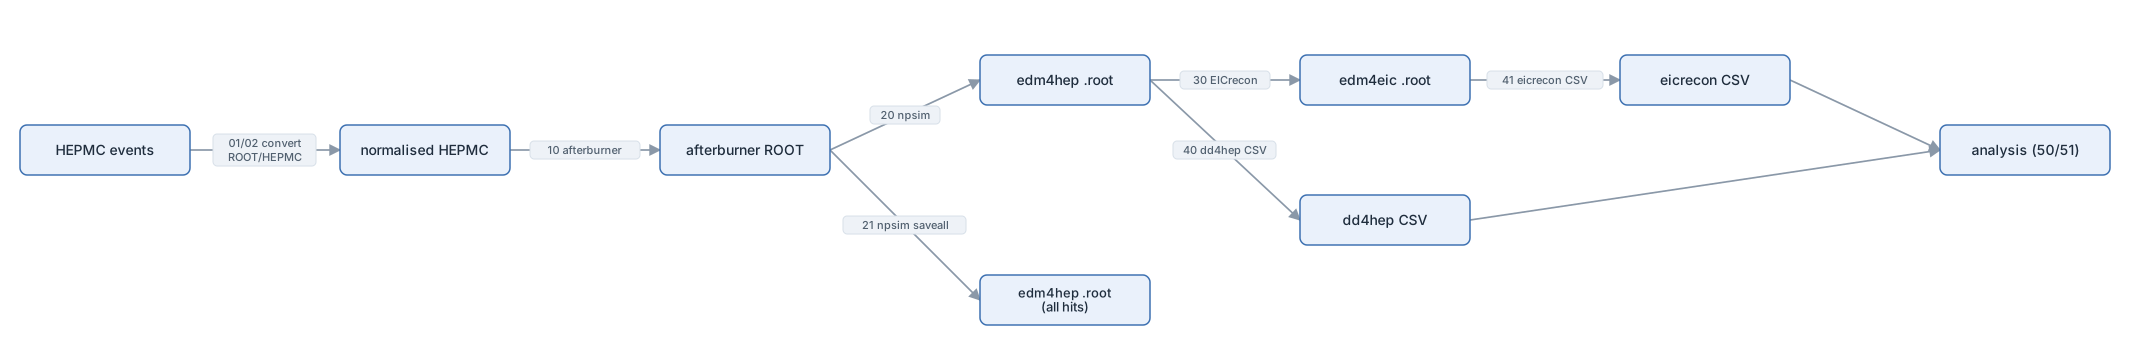
Scripts
| Script | Purpose |
|---|---|
01_root_hepmc_klam_convert.py | ROOT → HEPMC for KLam events |
02_root_hepmc_pin_convert.py | ROOT → HEPMC for π⁻ events |
10_create_afterburner_jobs.py | Apply beam-effects afterburner to HEPMC |
11_create_background_jobs.py | Merge in the background cocktail (bg_merger stage) |
20_create_npsim_jobs.py | Run npsim (DD4hep + Geant4) detector simulation |
21_create_npsim_saveall_jobs.py | Same as above, but keeping all hits incl. tracking volumes |
22_create_npsim_background_jobs.py | npsim over background-merged HEPMC |
30_create_eicrecon_jobs.py | Run EICrecon reconstruction |
40_csv_convert.py <stage> | One CSV script for every csv stage — runs the config's converter macros (edm4hep_* for csv_dd4hep, edm4eic_* for csv_eicrecon). See CSV Convert. |
50_create_analysis_jobs.py | Run physics analysis on CSV |
51_create_root_analysis_jobs.py | Run physics analysis directly on ROOT |
generate_datasets.py | Universal dataset-card producer (local glob / --rucio / --files) |
datasets.py | Card schema, config loader, run_card_pipeline |
rucio.py | Rucio dataset discovery (official campaigns) |
job_creator.py | Shared JobCreator class — see Job Creator |
scripts/collect_job_stats.py | Aggregate timings / exit codes across a campaign |
Each NN_*.py stage script is the same shape: load the YAML config, read the stage's dataset cards, render one container script per input file, and emit SLURM job-array submitters. The two former CSV scripts (40_create_csv_dd4hep_jobs.py / 41_create_csv_eicrecon_jobs.py) are now the single 40_csv_convert.py <stage>; which converters run is entirely the config's <stage>.macros list.
Configuration
Each campaign has its own self-contained YAML file under configs/, e.g.:
config-msf-26-07.yaml— meson-structure, 26.07config-msf-26-07-background.yaml— meson-structure with background cocktailconfig-off-26-06.yaml— official campaign (RECO already on Rucio)
These files set the campaign's base directory, container image, beam energies, event count, per-stage input/output paths, and each csv stage's macros: list. There is no inheritance — open one file and you see the whole picture. See the Campaigns page for details and conventions.
Continue reading
- Job Creator — the shared
JobCreatorclass. - Campaigns — config-file conventions, list of campaigns, and how to start a new one.